AI & LLMs
EmbeddingGemma 2 puts multimodal search on a phone
Google DeepMind's EmbeddingGemma 2 maps text, code, images, video and audio into one vector space with 740M parameters. Text-only use needs about 191 MB of RAM.
Open-weight model releases, meaning models whose weights can be downloaded and run outside the vendor's cloud: GLM, Qwen and Granite launches, the licenses attached to them, and tools like Ollama that run them locally. Each story states the parameter count, license terms and hardware needed.
Google DeepMind's EmbeddingGemma 2 maps text, code, images, video and audio into one vector space with 740M parameters. Text-only use needs about 191 MB of RAM.
AWS's Strands Decider 2B is an open-source model that picks from a list instead of writing text. It answers in 115 ms on an RTX 3090 and scores 72.3% on JevBench.

Mistral Large 4 is a 1.05T-parameter open-weight MoE model with a 1M-token context, in API preview at $1.36 per million input tokens. Weights follow in October.
Reflection AI's Beam has 501B parameters but uses 23B per token, scores 80.9 on SWE-Bench Verified, and ships weights under Apache 2.0 later in October.
Cloudflare's Clef (27B) and Clef-flash (9B) answer typed questions instead of writing text, at 209 ms and 39 ms median latency, under Apache 2.0.
Aleph Alpha released Kolibri 1 on October 3: a 78.1B-parameter open model with 3.46B active, built for German and English, under the Apache 2.0 license.
Ai2 released AstaBrief 8B, an Apache 2.0 model on Qwen3-8B that writes cited research reports in 51.1 seconds, 3.5x faster than Asta's Thinking mode.
The Qwen Research License lets anyone download Qwen-Image-2.1 but limits it to research or evaluation. Commercial use needs a separate license from Qwen.

Xiaomi's MiMo-V2.6-Pro has 1.02 trillion parameters, 42 billion active, a 1M-token context and MIT-licensed weights, but needs about 680 GB of GPU memory.
NVIDIA's Kumo Tabular predicts from a labeled table in one pass, with no training run. It ranks first on TabArena at 1,950 Elo, in sizes from 28M to 215M.
H Company's Holo4-27B scores 61.7% on OSWorld 2.0 at $1.22 a task, but only its Apache 2.0 sibling, 35B-A3B, can be self-hosted commercially.
A typed-decision model fills in fixed questions with typed answers and a confidence score. Laya's 421M open weights let you verify that yourself.
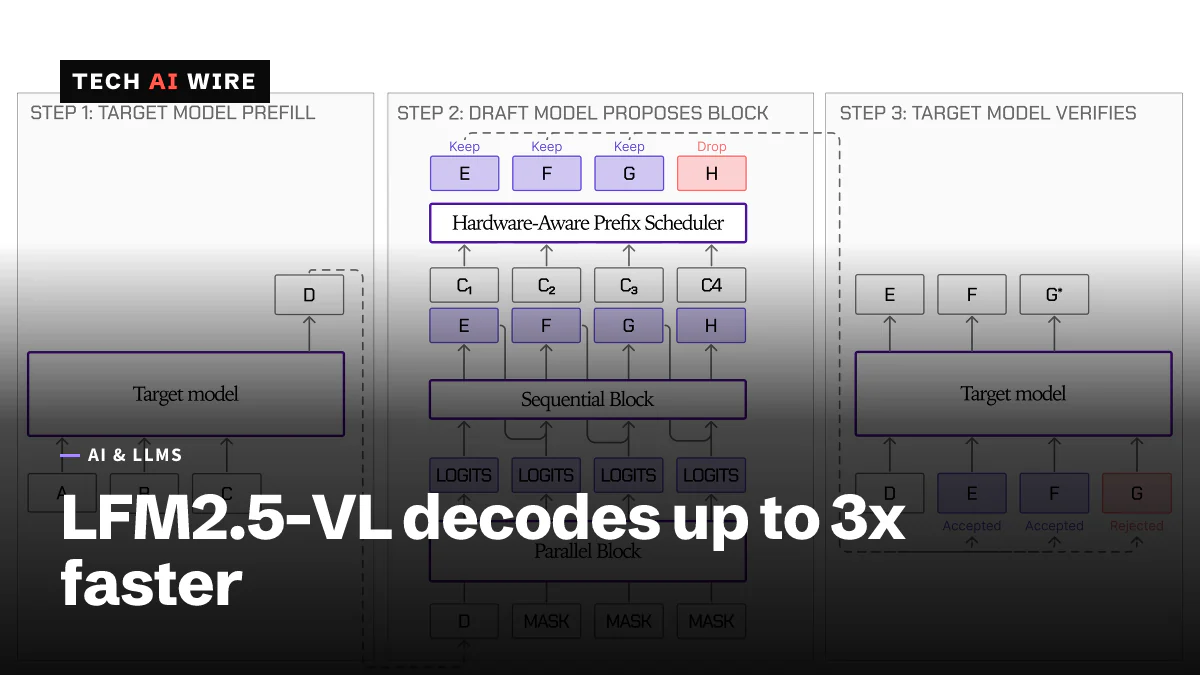
Liquid AI's 280M-parameter LFM2.5-VL-DSpark draft model decodes its 3B vision model up to 3.13x faster on an M5 Max, with identical output.
Qwen-Image-2.1 puts 7 billion parameters and native transparency in a downloadable image model. Its license bars commercial use without permission.
Laya returns typed decisions in 32.8 milliseconds from 421M parameters under Apache 2.0. Its zero-shot accuracy is close to chance.
Salesforce says Koa makes 3x fewer errors on its own CRM Bench, but the weights are proprietary and the model runs only on Salesforce infrastructure.
Qwen3.5-9B runs full attention on only 8 of its 32 layers, so its KV cache costs 32KB per token. That ratio decides whether it fits in 8GB.
Mistral raised €3 billion at a €21 billion valuation, nearly double its last round. It plans 1 GW of European compute by 2030 and will host rivals' open weights.
Z.ai's flagship GLM-5.3 weights are on Hugging Face after a safety review delay. The license is not MIT, and the model needs at least eight high-end GPUs.
Alibaba released Qwen3.8-Flash-Next on August 26, 2026. It activates 6B of 125B parameters per token, costs $0.16 per million input tokens, and previews Qwen4.
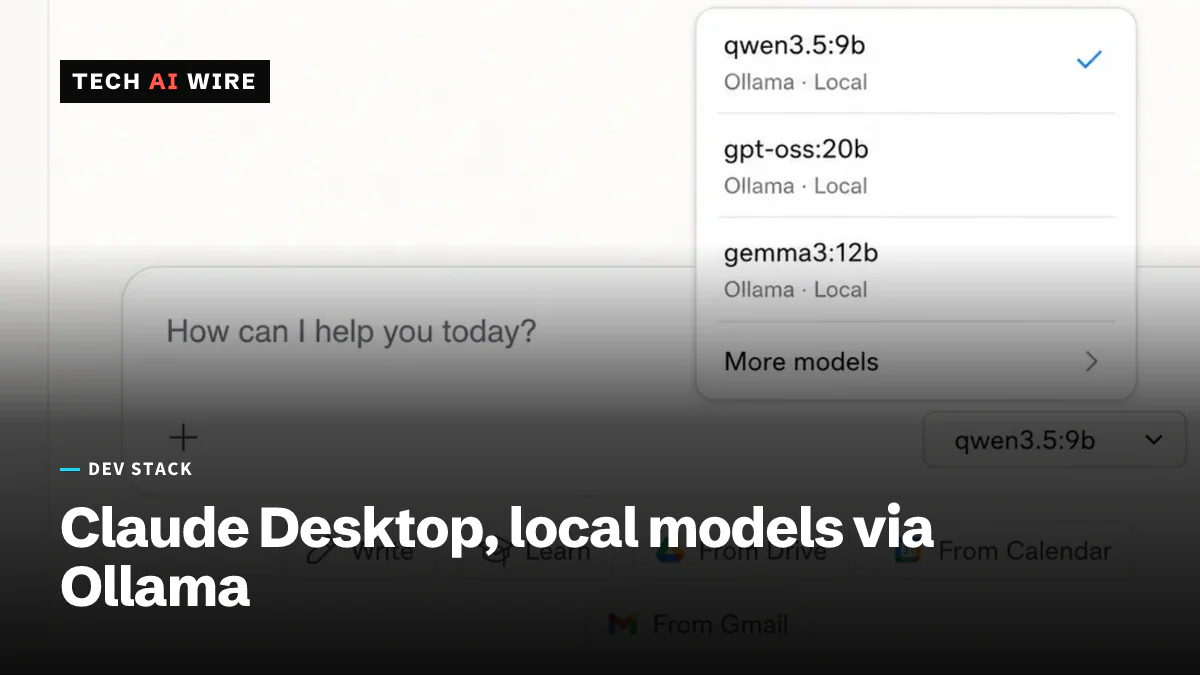
Ollama 0.33.0 adds a local proxy that swaps the model behind Anthropic's Claude Desktop app for an open one. A spring attempt failed on model-ID checks.
Z.ai released GLM-5.3-Flash under MIT with 320B parameters. IBM released Granite 4.2 under Apache 2.0 at 3B to 30B. They suit very different hardware.
One email every Friday with the week's top stories from all six desks: AI, dev tools, coding, the tech industry, startups and what's next. Free, no spam.