Nanbeige4.3-33B open model tops Qwen on agent coding
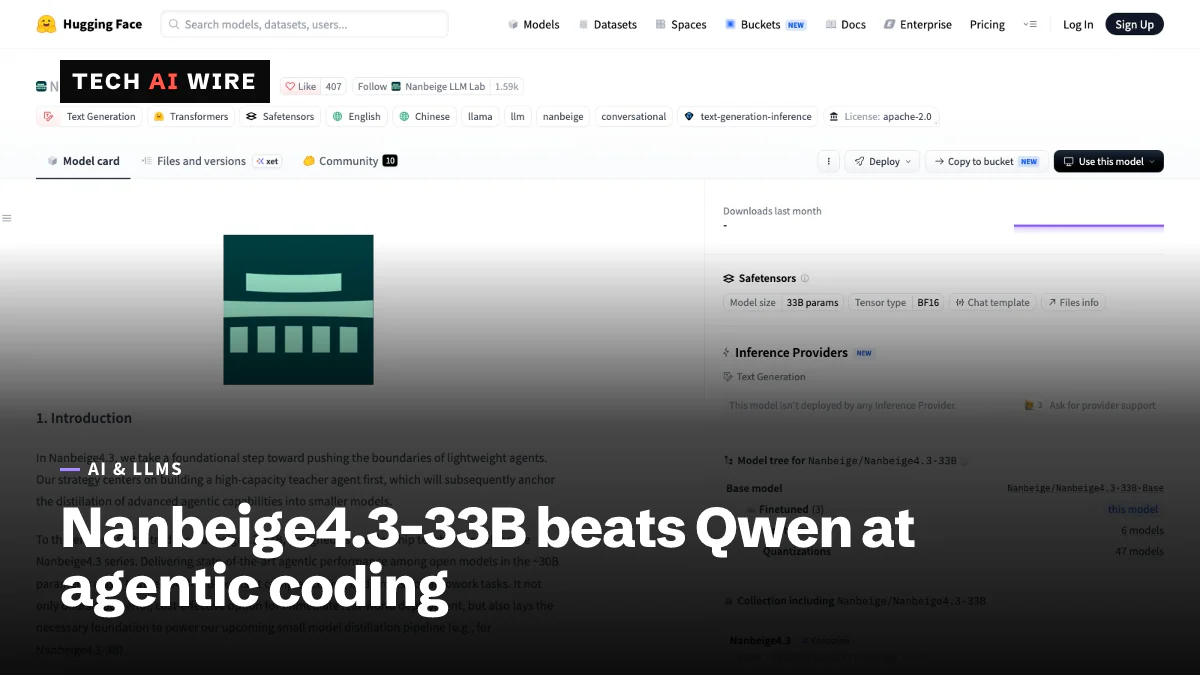
BOSS Zhipin's Nanbeige lab released Nanbeige4.3-33B under Apache 2.0, claiming 80.9 on Terminal-Bench 2.1 against 73.0 for Qwen3.8-27B.
4 min read
Drafted with AI from the sources linked in this article, then fact-checked and edited by Claire Whitmore before publishing. How we work
By the numbers
- parameters, all used for every token
- 33B
- tokens of context
- 524,288
- license, commercial use allowed
- Apache 2.0
- Nanbeige4.3-33B
- 80.9
- Qwen3.8-27B
- 73
- Muse-Glimmer-30B
- 61.8
- Gemma4-31B
- 47.2
Nanbeige LLM Lab, the AI research team of Chinese recruitment platform BOSS Zhipin, has released Nanbeige4.3-33B as open weights under the Apache 2.0 license. The weights went up on Hugging Face on October 24, 2026. On the lab's own tests, the 33-billion-parameter model beats Qwen3.8-27B at most agent-style coding tasks.
Open weights means anyone can download the model files and run them on their own hardware. Apache 2.0 allows commercial use with few conditions.
What Nanbeige4.3-33B is
The model card on Hugging Face calls it the "flagship teacher model" of the Nanbeige4.3 series. A teacher model is a large model used to train smaller ones, a process called distillation. Data Studios reports that Nanbeige4.3-3B is named as the first smaller "student" model. No date has been given for it.
The model is built for agentic work. That means tasks where the model plans steps and calls tools, such as a terminal or a code editor, rather than only answering a question. The card says it "excels at complex coding and professional cowork tasks."
Key facts from the card and Data Studios:
- Size: about 33 billion parameters in a dense design. Every parameter works on every token, unlike mixture-of-experts models that use only part of their weights at a time.
- Context: 524,288 tokens, the amount of text it can read at once.
- Languages: English and Chinese.
- Thinking mode: on by default. The card recommends keeping earlier reasoning in multi-turn tool use and code-agent work.
Nanbeige's earlier public models were all small, 3-billion-parameter releases, Data Studios says. Startup Fortune notes the 3B line came out earlier in 2026.
The benchmark claims
The card claims "state-of-the-art agentic performance among open models in the ~30B parameter class." It compares the model with Qwen3.8-27B, Muse-Glimmer-30B and Gemma4-31B.
| Benchmark | Nanbeige4.3-33B | Qwen3.8-27B | Gemma4-31B |
|---|---|---|---|
| Terminal-Bench 2.1 | 80.9 | 73.0 | 47.2 |
| DeepSWE | 65.5 | 42.5 | 2.7 |
| SWE-Bench Pro | 60.3 | 61.7 | 51.2 |
| NL2Repo | 53.0 | 48.3 | 33.8 |
| Automation Bench | 54.2 | 38.3 | 9.7 |
| JobBench | 44.8 | 34.5 | 9.0 |
| GPQA Diamond | 89.5 | 89.2 | 91.3 |
| AIME 2026 | 95.2 | 94.5 | 89.2 |
Startup Fortune counts a win over Qwen3.8-27B on seven of eight agentic-coding tests. Qwen stays ahead on SWE-Bench Pro, a test of fixing real software issues, and on GDPval. Gemma4-31B leads on GPQA Diamond, a graduate-level science quiz.
Every number is Nanbeige's own. Data Studios points out that the lab adapted several test setups, so the scores do not line up directly with public leaderboards. For example, the card says NL2Repo was run through Claude Code. No technical report has been published, and the training data is not disclosed.
How to run it
The card gives setup recipes for Transformers, SGLang, vLLM and Docker Model Runner. Its serving examples split the model across four GPUs. The card does not state a minimum amount of GPU memory.
Data Studios estimates the full-precision weights at about 66 GB. It also estimates that a full-length context would need about 104 GiB of extra memory for the model's working cache. Both are the outlet's own calculations, not figures from the card.
Smaller hardware is possible with quantization, which shrinks the weights by storing numbers with fewer bits. Startup Fortune reports that a 4-bit version runs on a single 24 GB graphics card. It adds that the large cache then limits how much context you can actually use. Hugging Face lists 47 community quantizations, and Data Studios found no hosted API serving the model at the time.
What this means for developers
Nanbeige4.3-33B is another strong sign that capable coding agents can run on hardware a team owns. It follows Recursive's Flint, an Apache-licensed 40B coding model released days earlier.
- Test it on your own tasks first. The scores are self-reported and use adapted harnesses. Run it on a sample of your real issues before trusting the table.
- Compare it with Qwen3.8-27B side by side. Qwen still leads on SWE-Bench Pro, which is closest to fixing issues in an existing codebase.
- Budget memory for context, not just weights. A 24 GB card can load a 4-bit copy, but long agent sessions need room for the cache.
- Follow the card's settings. Use the recommended sampling values and keep thinking enabled for tool use, as the card recommends for agent work.
- Check the license chain. Apache 2.0 covers the official weights. Community quantizations are separate uploads, so confirm each one keeps the same terms.
Sources
- Nanbeige4.3-33B model card - Hugging Face
- Nanbeige's new 33B open model takes aim at Qwen and Gemma on coding - Startup Fortune
- Nanbeige4.3-33B: Apache 2.0 dense agentic coding model with 512K context and benchmarks - Data Studios
Related articles
Kimi K3.1 Pro nears Opus 5.5 at coding, cuts cyber skills
Moonshot's Kimi K3.1 Pro scores 65.7% on Terminal-Bench 4.0, a point behind Claude Opus 5.5. Its weights are due by November 4, with cyber data removed.
Reflection Beam open weights land under Apache 2.0
Reflection put Beam's 501B-parameter weights on Hugging Face on October 16, 2026 under Apache 2.0. The FP8 and 4-bit versions fit on one 8-GPU server.
NVIDIA Kumo Tabular tops TabArena with open weights
NVIDIA's Kumo Tabular predicts from a labeled table in one pass, with no training run. It ranks first on TabArena at 1,950 Elo, in sizes from 28M to 215M.
The weekly digest
One email every Friday with the week's top stories from all six desks: AI, dev tools, coding, the tech industry, startups and what's next. Free, no spam.