Dev Stack
PyTorch 2.15 speeds MoE decoding on Macs up to 6.5x
PyTorch 2.15 adds FP8 tensors on Apple GPUs and new Metal kernels. Qwen3.6-35B-A3B decoding on an M3 Ultra jumps from 9.4 to 61.3 tokens a second.
Running language models locally instead of in the cloud: Ollama proxies that put an open model behind a desktop app, hardware judged by memory and bandwidth, Windows modes for local models, and on-device search products. Each story states the memory needed and what works.
PyTorch 2.15 adds FP8 tensors on Apple GPUs and new Metal kernels. Qwen3.6-35B-A3B decoding on an M3 Ultra jumps from 9.4 to 61.3 tokens a second.
AMD's open-source local agent app now runs one agent, shrinks its Windows Python setup from 0.9GB to 0.1GB and stops crashing on 16GB laptops.
Nvidia RTX Spark laptops from six makers went on sale on October 16 from $2,599, with up to 128GB of memory and a new 74B open model, Nemotron 3.5 Bolt.
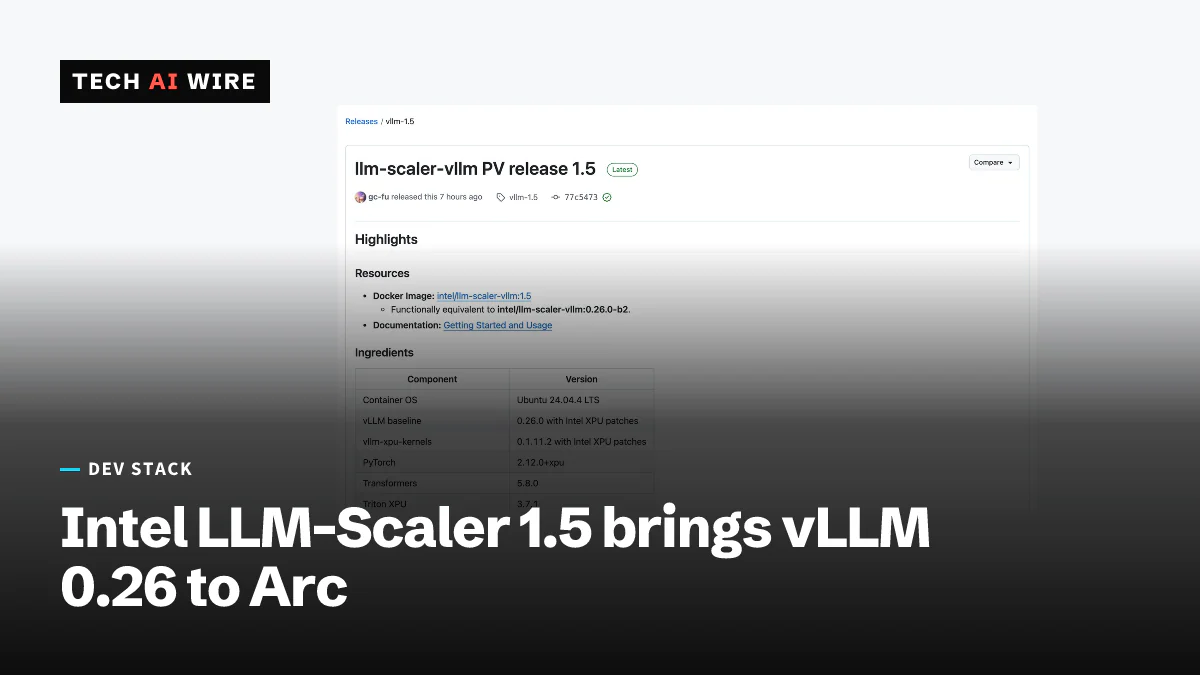
Intel's LLM-Scaler-vLLM 1.5 moves its Arc GPU Docker stack from vLLM 0.14 to 0.26 and adds Gemma 4 and Qwen3.8 models plus FP8 and INT4 options.
Microsoft's Surface Laptop Ultra pairs Nvidia's RTX Spark chip with up to 128 GB of shared memory. It costs from $2,599.99, with preorders open and shipping October 16.
Microsoft opened US preorders for the Surface RTX Spark Dev Box at $5,999 on October 7, 2026, with 128GB of unified memory for local AI models.
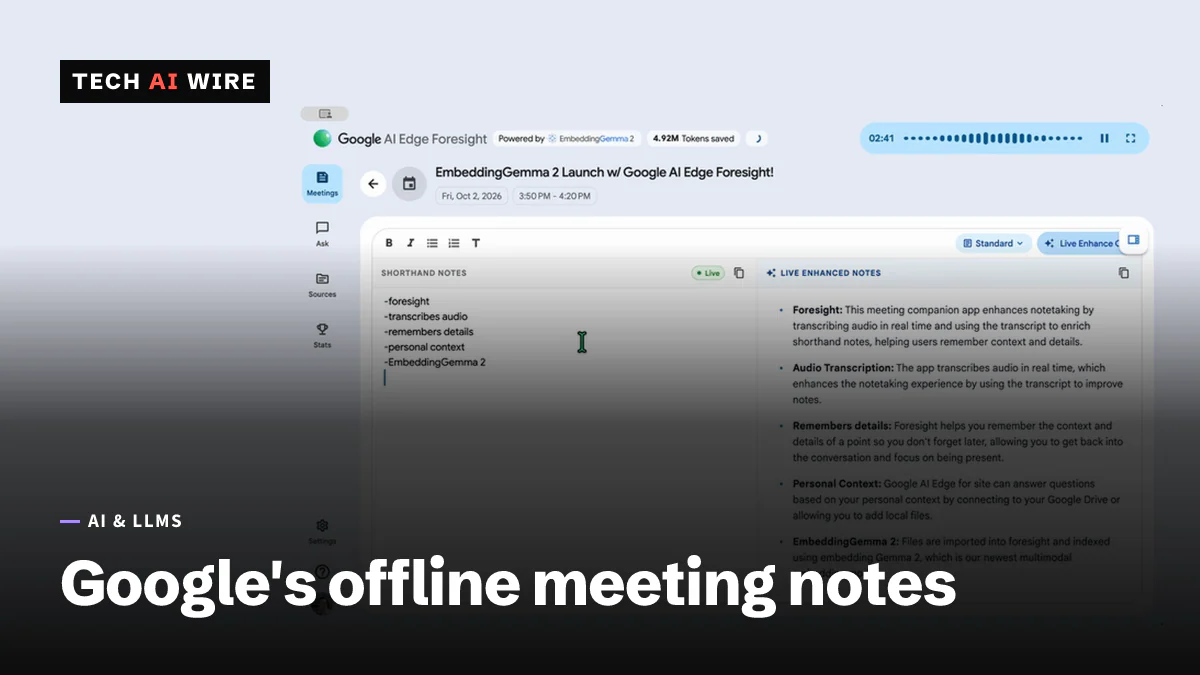
Google AI Edge Foresight, an experimental Mac app, turns shorthand into meeting notes on-device with Gemma 4 and the 740M-parameter EmbeddingGemma 2.
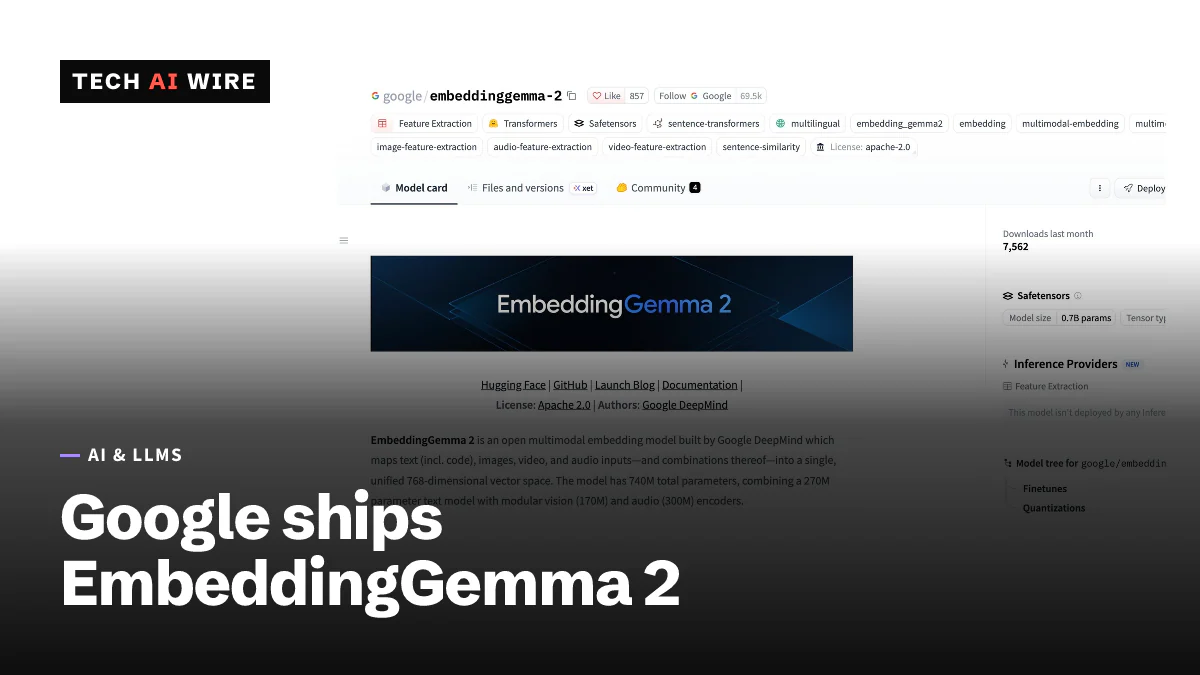
Google DeepMind's EmbeddingGemma 2 maps text, code, images, video and audio into one vector space with 740M parameters. Text-only use needs about 191 MB of RAM.
AWS's Strands Decider 2B is an open-source model that picks from a list instead of writing text. It answers in 115 ms on an RTX 3090 and scores 72.3% on JevBench.
A new MIT-licensed command-line tool turns off Apple Intelligence on macOS 27, deletes its on-device models and stops macOS from downloading them again.
Aleph Alpha released Kolibri 1 on October 3: a 78.1B-parameter open model with 3.46B active, built for German and English, under the Apache 2.0 license.
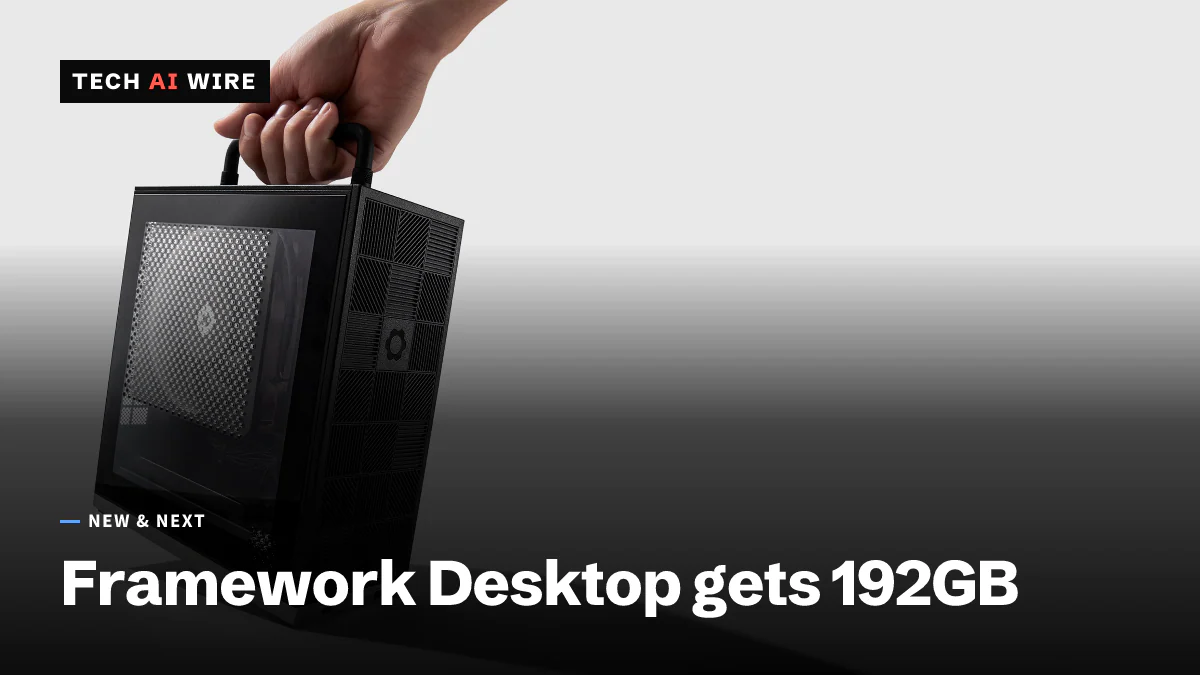
Framework opened pre-orders on September 30, 2026 for a 192GB Framework Desktop with AMD's Ryzen AI Max+ PRO 495, at $6,799 and shipping in November.
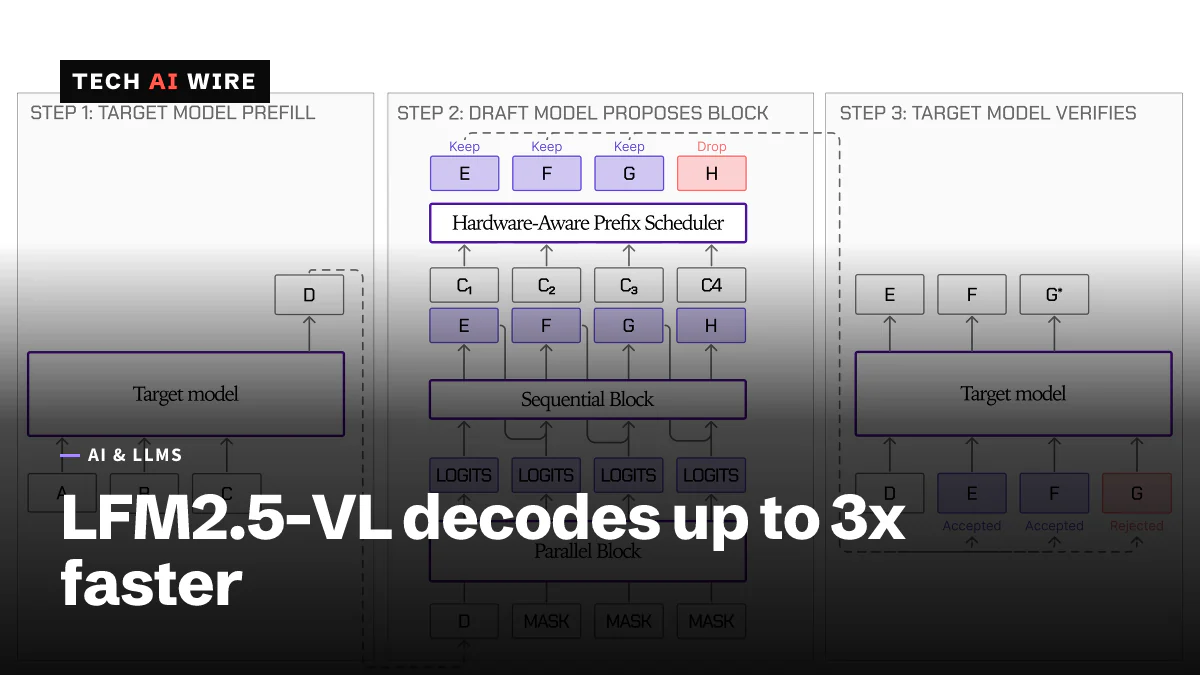
Liquid AI's 280M-parameter LFM2.5-VL-DSpark draft model decodes its 3B vision model up to 3.13x faster on an M5 Max, with identical output.
Qwen3.5-9B runs full attention on only 8 of its 32 layers, so its KV cache costs 32KB per token. That ratio decides whether it fits in 8GB.
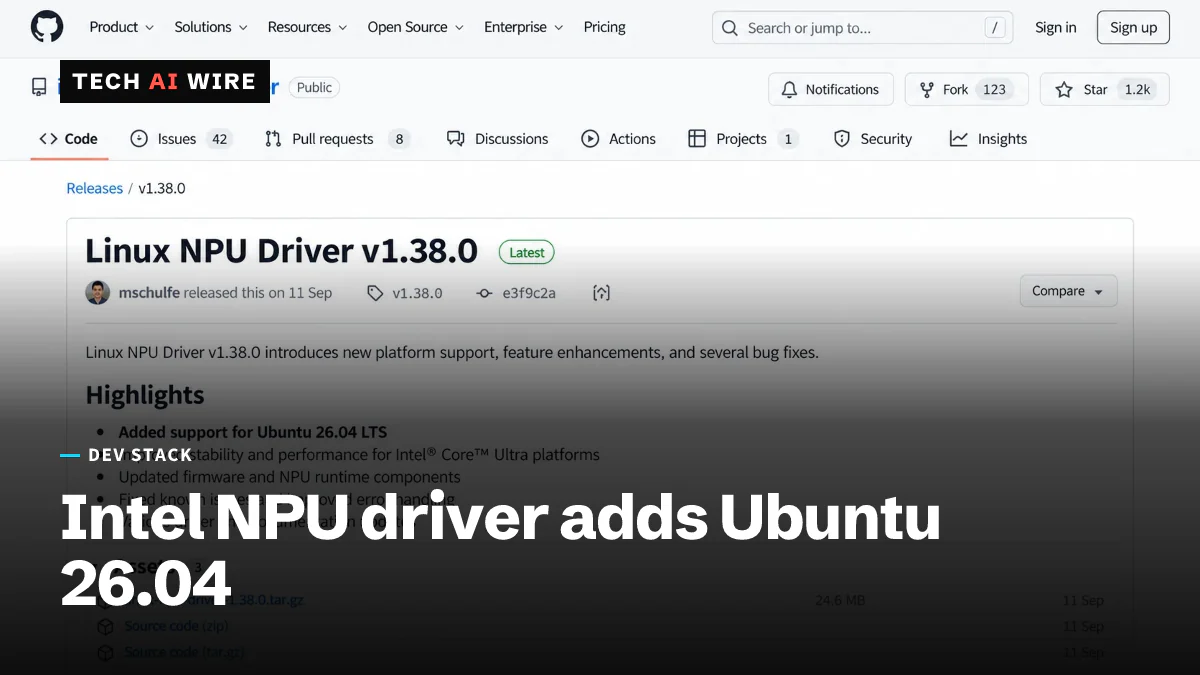
Intel's NPU driver 1.38 officially supports Ubuntu 26.04 LTS about five months late, with 322 tests passing across five processor generations.
Project Zenith is a developer-focused Windows 11 experience for running 30B-plus parameter models locally, on PCs with 64GB of unified memory.
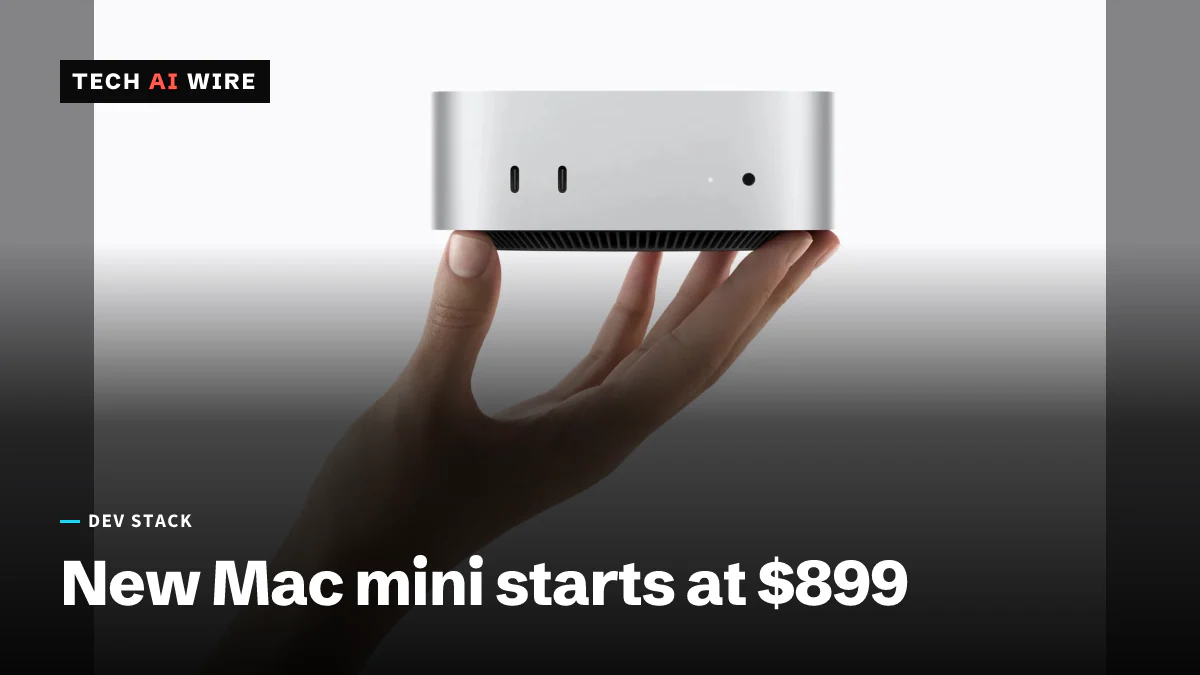
Apple announced new Mac mini and Mac Studio models on August 25, 2026, shipping September 22. For local model work, the memory ceiling matters more than the AI multipliers.
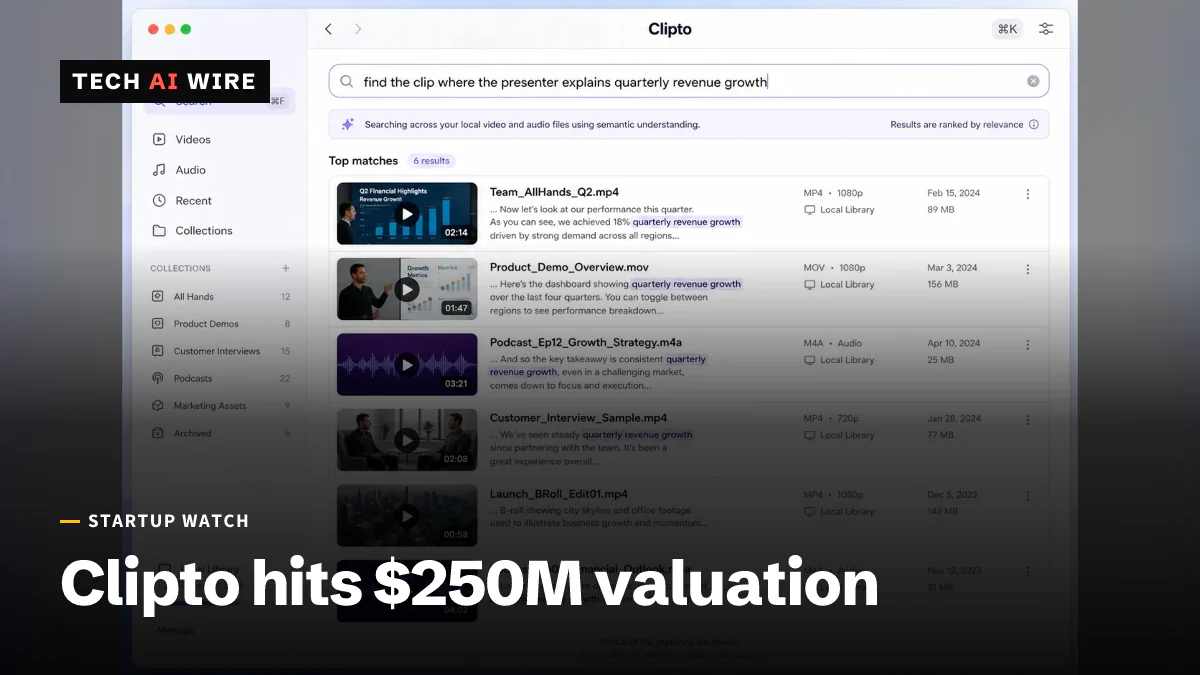
Clipto said on August 31, 2026 that it raised $15 million at a $250 million valuation. Its search index runs on the user's own machine instead of the cloud.
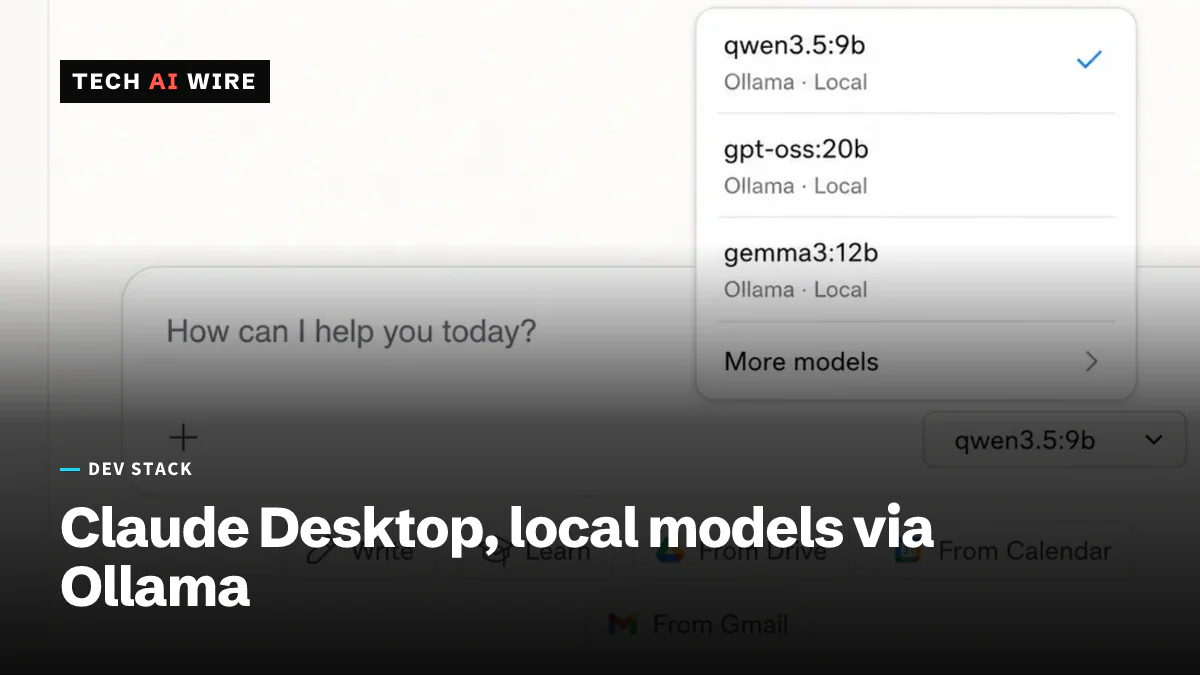
Ollama 0.33.0 adds a local proxy that swaps the model behind Anthropic's Claude Desktop app for an open one. A spring attempt failed on model-ID checks.
One email every Friday with the week's top stories from all six desks: AI, dev tools, coding, the tech industry, startups and what's next. Free, no spam.