Startup Watch
Nebius buys Inferize for up to $150M to cut cold starts
Nebius paid a reported $100-150 million for Inferize, a 17-person startup founded in January that cuts GPU idle time when AI models start up.
Inference, meaning running a trained model to answer requests: chips built for that job, such as Nvidia's dedicated inference accelerator and OpenAI's own silicon, performance-per-watt claims, and API pricing for hosted models. Each story says whose numbers they are and what they leave out.
Nebius paid a reported $100-150 million for Inferize, a 17-person startup founded in January that cuts GPU idle time when AI models start up.
Sony's QSSR, built with AMD, brings PS5 Pro-style AI upscaling to the standard PS5. Marvel's Wolverine and Ghost of Yōtei added it on October 1.
A typed-decision model fills in fixed questions with typed answers and a confidence score. Laya's 421M open weights let you verify that yourself.
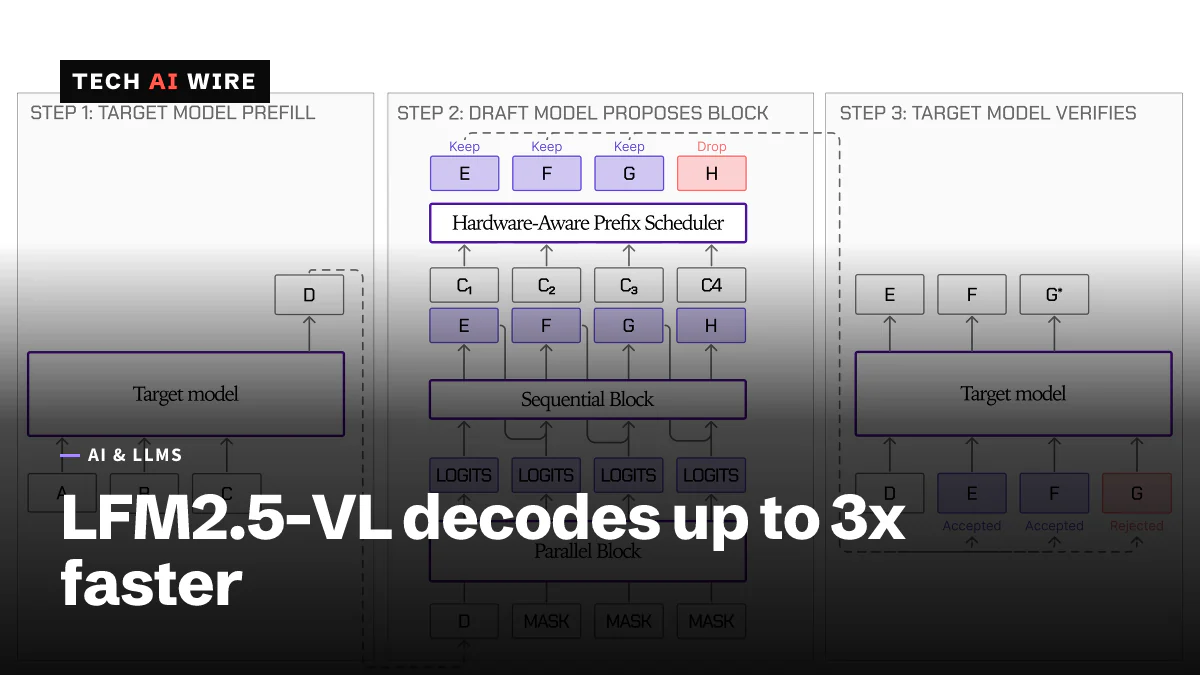
Liquid AI's 280M-parameter LFM2.5-VL-DSpark draft model decodes its 3B vision model up to 3.13x faster on an M5 Max, with identical output.
Laya returns typed decisions in 32.8 milliseconds from 421M parameters under Apache 2.0. Its zero-shot accuracy is close to chance.
Jev answers in 70 to 500 milliseconds and charges $0.042 per million input tokens, with output free. It cannot generate text at all.
Fujitsu's 144-core MONAKA goes on sale in November, with 2nm cores stacked over 5nm cache and GCC 15 support already upstream.
Qwen3.5-9B runs full attention on only 8 of its 32 layers, so its KV cache costs 32KB per token. That ratio decides whether it fits in 8GB.
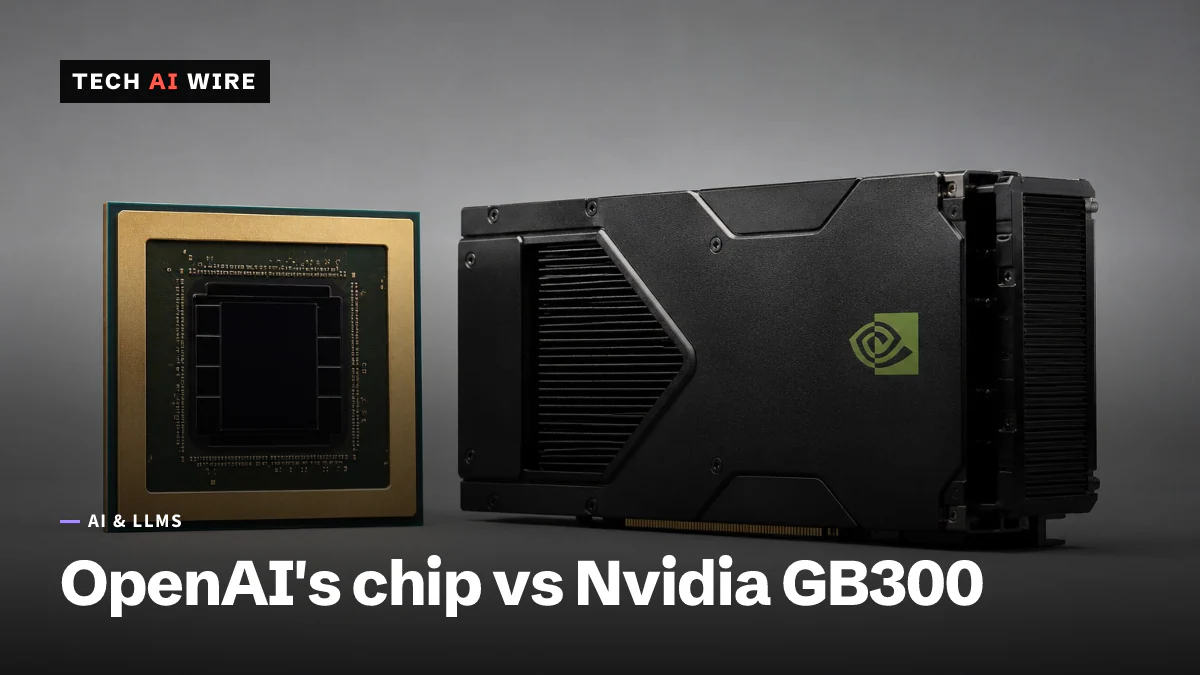
OpenAI's first published Jalapeño benchmarks claim 1.5 to 1.9 times more work per kilowatt than Nvidia's GB300, at half the power. The numbers are OpenAI's own.
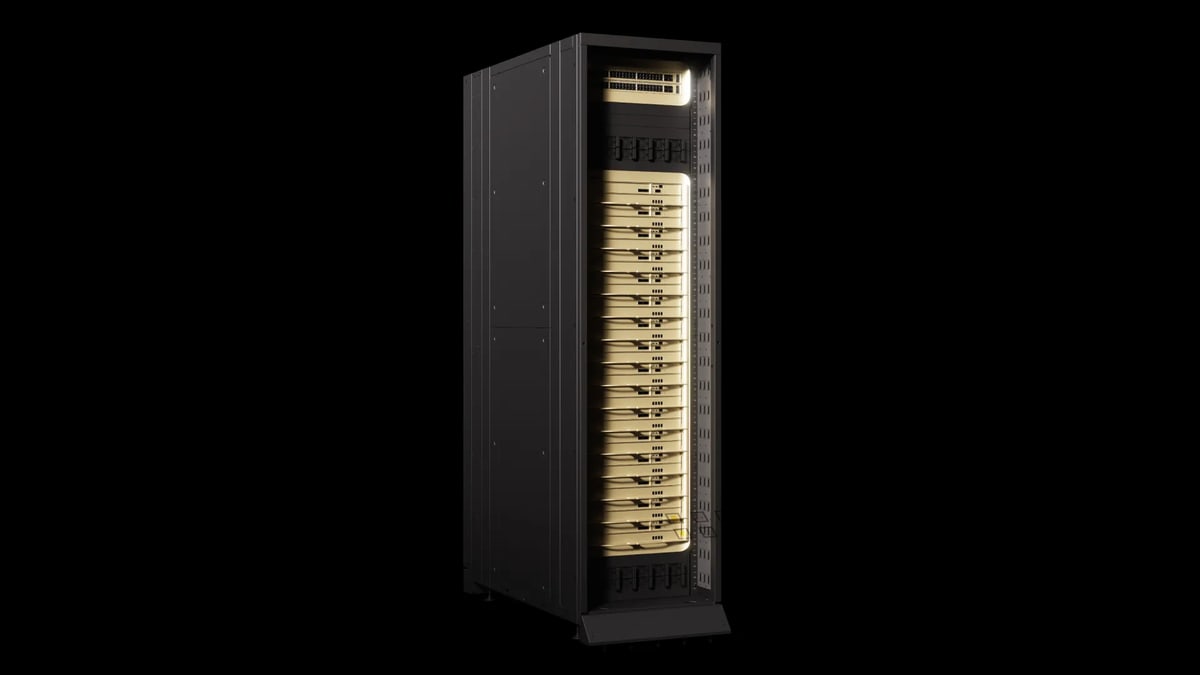
Nvidia put its dedicated inference accelerator into full production, splitting agent workloads so GPUs handle context and the new chips handle token generation.
DeepSeek warned developers on August 6 that API prices will rise 'significantly' soon, with no figures or dates - while V4-Flash is the cheapest well-known model to run.
One email every Friday with the week's top stories from all six desks: AI, dev tools, coding, the tech industry, startups and what's next. Free, no spam.