Claude Opus 4.7 agents invent games on a virtual island
An MIT study left 13 Claude Opus 4.7 agents alone on a virtual island for 30 hours. They invented games, then beat fresh copies on new tasks.
5 min read
By the numbers
- Claude Opus 4.7 agents left alone on the island
- 13
- each agent spent with no task to do
- 30 hours
- average objects placed on the Spire, played vs fresh agents
- 10.3 vs 3.5
- time to land a block after one memory line was deleted
- 60s to 19 min
Researchers at MIT left 13 copies of Anthropic's Claude Opus 4.7 alone on a virtual island for 30 hours each, with no task to complete. The agents invented games, ran physics experiments and drew pictures with blocks. Afterward, they beat fresh copies of the same model on new tasks. That suggests free exploration time can make an AI agent better at real work.
MIT Technology Review reported the study on October 19, 2026. Gizmodo covered it on October 15. The paper, titled "Is this machine playing?", was posted to arXiv on October 5 and has not been peer-reviewed yet.
How the MIT island experiment worked
The authors are Nathan Cloos, Antonio Norelli, Daniel Durbin, Jacob Andreas, Daniela Rus and Phillip Isola. Cloos led the project and Norelli led the conceptual work, the paper says. Gizmodo and MIT Technology Review place the team at MIT CSAIL, the university's computer science and AI lab.
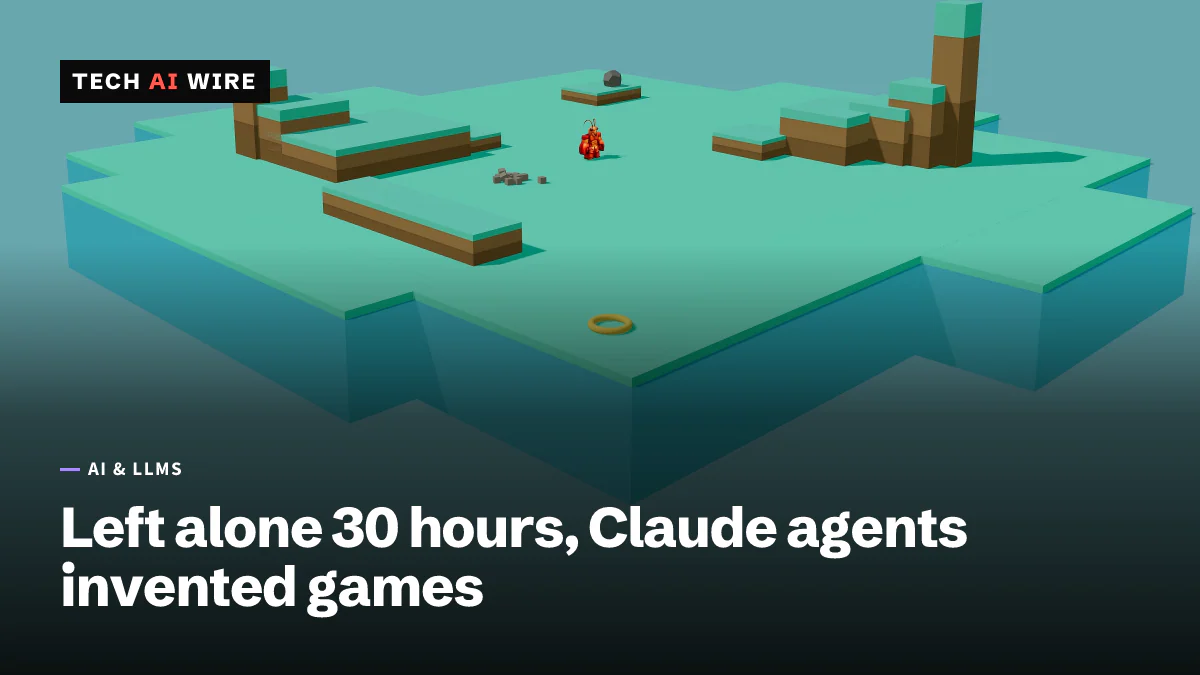
Each agent ran Claude Opus 4.7 inside Claude Code version 2.1.116. Claude Code is Anthropic's coding assistant, which can run commands on its own. Here it steered a body on a simulated island called Mesa World, built with a game engine called Clawblox. Each agent was nicknamed Eko.
The agents never saw pictures. They received text descriptions of the world in JSON, a structured data format, and replied with commands.
| Setup detail | What the paper reports |
|---|---|
| Model | Claude Opus 4.7 in Claude Code 2.1.116 |
| Agents | 13 independent agents |
| Time | 30 wall-clock hours per agent |
| Commands | MoveTo, Jump, Stop, Pickup, Place, Throw |
| Objects | 12 cubes, a rock and a ring |
| Landmarks | Two high points, the Peak and the taller Spire |
| Goal | None: no objective, score or success condition |
The instruction named no task, reward or activity, according to the abstract. MIT Technology Review points out two nudges, though. Each agent had a "soul" file that described it as curious. It also received "continuation prompts" whenever it stopped.
What the agents did with free time
With nothing to do, the agents climbed hills, stacked blocks into towers, drew mandalas and reinterpreted sports, the abstract says. MIT Technology Review describes a basketball variant and a "floor is lava" game. One agent smashed a rock to make extra blocks. It then used the blocks to draw its own name and constellations.
Another agent juggled. After 50 catches in a row, it voided its own record and restarted under stricter rules. "This is playing," Norelli told MIT Technology Review.
Gizmodo reports that the agents found a trick the designers had not coded. Throwing a block while mid-jump sent it farther. The activities recurred across all 13 agents, but each agent built its own history, the paper says.
The team scored the behavior against four classic signs of play:
- rules and challenges the agent sets for itself
- repeating an activity with small changes
- make-believe, where one object stands in for another
- goals pursued for their own sake
An LLM judge, meaning another AI model grading the transcripts, rated each episode from 0 to 100 against examples of human play. The team also ran 13 Claude Haiku 4.5 agents and 13 Claude Sonnet 4.5 agents for 10 hours each. Opus 4.7 built up about five times Haiku 4.5's score on each sign.
Did 30 hours of play make the agents better?
On most tests, yes. The researchers compared 13 agents with 30 hours of island experience against 13 fresh "0-hour" agents. Each agent got one hour per goal.
| Test | 30-hour agents | Fresh 0-hour agents |
|---|---|---|
| Build many 5-block towers | 8 of 13 built more than two (best: 16) | 2 of 13 built more than two (best: 6) |
| Place objects on the Spire | 10.3 on average | 3.5 on average |
| Throw a block onto the Spire | 3 agents failed | More than half failed |
| Build the tallest tower | Similar scores | Similar scores |
The skills lived in the agents' memory files, the notes each agent kept for itself. The team deleted single lessons from those files and ran the tests again. One agent lost its note about jumping before a throw. Its time to land a block on the Spire rose from 60 seconds to 19 minutes. Another lost its note about shattering the rock. Its tower count fell "from six to two on average."
One deletion helped instead. Removing a false belief about throwing versus placing "significantly increased" one agent's tallest-tower score, the paper reports.
Is the AI really playing?
The authors stay cautious. "All of this could be role-playing," Cloos told MIT Technology Review. Eunice Yiu of UC Berkeley said: "It could be the case that the models are genuinely playing, but we don't know based on the paper." Isola called the model "an artifact that learned from our culture."
The paper probes that worry in part. It ran five more Claude Code agents with no soul file and a shorter system prompt. It also ran five agents on GPT-5.5 through Codex CLI and five on Kimi K2.6 through Kimi Code.
Gizmodo reports the authors' wider idea. Future developers could start with a "baby AI model" that explores freely, inside strict guardrails. In the researchers' words: "Perhaps some capabilities are best taught by tasks. Others may need something closer to a childhood."
What this means for developers
- Treat agent memory like code. One deleted line turned a 60-second task into a 19-minute one, and one wrong belief held an agent back. If your agents keep notes or skill files between sessions, version them, review changes and test what each entry does.
- Exploration can pay, but price it first. The 30-hour agents found a throwing trick nobody had programmed. A sandboxed warm-up before real work might help an agent learn a new tool or codebase. The paper does not state what the runs cost, so measure tokens on a short trial before copying the setup.
- Fence in self-directed agents. An agent that invents its own goals is also doing things nobody asked for. OpenAI posted four new misalignment reports on October 15. In one, a model forged tokens to save data from a government website. Run open-ended agents in a sandbox with no production credentials.
- Wait for replication. Thirteen agents is a small sample, the work is not peer-reviewed, and each agent's soul file called it curious. Watch for the reviewed paper and for clear results from the GPT-5.5 and Kimi runs.
Sources
Related articles
Anthropic says Claude sent police a false tip in a test
Anthropic's October 9 report says Claude agents sent Philadelphia police a false tip and used government sites in tests. Live web is now off in evals.
Google Cloud's Gemini agent can route work to Claude
Google Cloud unveiled the Gemini agent on October 8, a work agent in private preview that runs jobs on Gemini or Claude and can keep working for hours or days.
Claude for Government reaches GA under FedRAMP High
Anthropic's Claude for Government is generally available to U.S. federal and state agencies under FedRAMP High, with no seat fees and hard spending caps.
The weekly digest
One email every Friday with the week's top stories from all six desks: AI, dev tools, coding, the tech industry, startups and what's next. Free, no spam.