Meta narrows web-crawling clause in its business terms
Meta cut the word "train" from a clause letting it crawl business customers' websites, days before its Commercial Terms take effect on October 30, 2026.
4 min read
By the numbers
- date Meta's new Commercial Terms take effect, 2026
- Oct 30
- businesses using Meta's AI agents in WhatsApp and Messenger
- 1M+
- mentions of robots.txt in the new terms
- 0
Meta has rewritten a clause in its new Commercial Terms that let it crawl the websites of its business customers and use the content to "train" its products. The revised text, live by October 17, 2026, drops the word "train" after a day of protest from news publishers. The terms still take effect on October 30, and almost any company that runs Meta ads is covered by them.
The Next Web and Unite.AI reported the change on October 17. Meta says the crawling language only ever applied to its ads and business products, and that the new wording simply spells that out.
What the clause says
The old Commercial Terms, dated March 6, 2024, had no crawling language at all, PPC Land reports. The new Section 1 lets Meta use "web scrapers, bots, robots, spiders, crawlers, and user agents" on domains "associated with your products or services." It also lets Meta "create test credentials," which means accounts set up to get into those sites.
A crawler is a program that visits web pages and copies their content automatically. The clause decides what Meta may do with what its crawlers copy.
| Version | What Meta may use crawled content for |
|---|---|
| Original, as archived on October 16 | "to provide, develop, improve, research, train" Meta's products |
| Revised, as archived on October 17 | "to provide, develop, improve, research, and maintain advertising and business products" |
Unite.AI reports that the licensing section also lost a sentence. The same revised clause appears in a preview of Meta's Self-Serve Ad Terms, which take effect on the same date.
Who is covered
The terms apply to Meta's business customers, which is a wide group. The Register lists anyone who runs ads or sends marketing messages, sells or lists products, builds apps, or manages a Page or Group. Nieman Lab found that almost every news publisher has at least one Meta business account, The Register adds. It also cites a Reuters count of at least a million businesses using Meta's AI agents in WhatsApp and Messenger.
There is no separate opt-out. Businesses accept the terms by continuing to use Meta's commercial products, and the only way to refuse is to stop using them.
Why publishers objected
Nieman Lab first reported the clause on October 15. The News/Media Alliance, which represents news publishers, attacked it the next day. "Meta's new commercial terms of use are outrageous and probably illegal," said Danielle Coffey, its president and CEO, in The Register. She said the terms could not be allowed to take effect on October 30.
Meta spokesperson Andy Stone called the early reports "false" on October 16. He said there was "no change to how Meta uses web crawlers." The update was "designed to make sure we're able to pull accurate information about products for sale on third-party websites," he wrote, according to PPC Land.
The fix has not settled the fight. The alliance says training was taken out of the listed uses but not expressly banned, The Next Web reports. PPC Land and The Register, writing on October 16 and 17, still described the clause as allowing training. Their reports were written around the time of the change.
The robots.txt gap
Robots.txt is a small file on a website that tells crawlers which pages they may visit. Meta says owners can use it. "Content owners can use robots.txt flags to indicate their preferences," Stone wrote on X.
The terms themselves never mention robots.txt, PPC Land and The Register both note. Eric Goldman, a law professor at Santa Clara University, told The Register the language does not expressly require Meta to honor it. Tech AI Wire reported in September that Cloudflare began offering a robots.txt rule against AI training, one of the few signals publishers have.
What this means for developers
- Read the October 30 terms now. If your company runs Meta ads, lists products or manages a Page, you accept these terms by doing nothing. Legal and marketing teams have under two weeks to decide.
- Do not rely on the word change alone. The revised clause drops "train," but the publishers' group says training is not expressly ruled out. Treat the clause as broad until Meta says otherwise in writing.
- Set your robots.txt rules on purpose. Meta points owners to robots.txt, though the terms do not promise to honor it. Name Meta's crawlers in the file and log their visits, so you can see what they actually do.
- Watch for test accounts. The clause lets Meta "create test credentials." Sites with sign-up walls should watch for new accounts tied to Meta's crawlers.
- Plan for the exit cost. The only refusal is to stop using Meta's business products. For most companies that is not a real option, which is why the exact wording matters.
Sources
- Meta drops 'train' from its website-crawling terms after backlash - The Next Web
- Meta Rewrites Web-Crawling Clause in Pending Commercial Terms - Unite.AI
- Meta's new terms let it crawl business websites to train AI from Oct 30 - PPC Land
- Meta grants itself right to scrape content from business customers for model training - The Register
Related articles
China drafts export curbs on AI models and chip designs
China's draft adds 23 AI technologies to its export control list, from models with 2 trillion parameters to chip designs. Comments close on November 15.
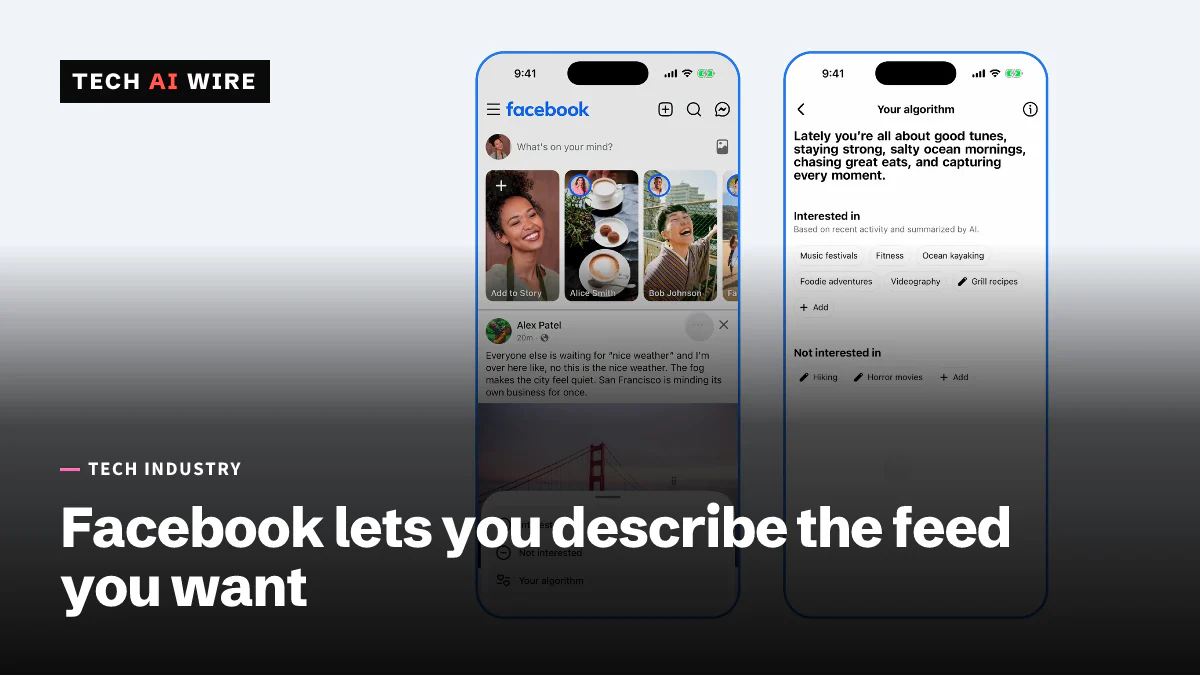
Facebook's Your Algorithm lets you describe your feed
Meta launched Your Algorithm on Facebook on October 13: users describe in their own words what they want more or less of in Feed and Reels.
UK regulator Ofcom investigates Meta over Instagram Instants
Ofcom is checking whether Meta skipped required safety risk assessments before launching Instagram Instants. Fines can reach £18 million or 10% of worldwide revenue.
The weekly digest
One email every Friday with the week's top stories from all six desks: AI, dev tools, coding, the tech industry, startups and what's next. Free, no spam.