AI & LLMs
Claude Sonnet 5.5 nears Opus 5.5 at half the price
Claude Sonnet 5.5 scores 70.6% on Terminal-Bench 4.0 at $2/$10 per million tokens, half Opus 5.5's price. Sonnet 4.5 retires on November 30, 2026.
The latest LLM coverage on Tech AI Wire.
Claude Sonnet 5.5 scores 70.6% on Terminal-Bench 4.0 at $2/$10 per million tokens, half Opus 5.5's price. Sonnet 4.5 retires on November 30, 2026.
Ai2 released AstaBrief 8B, an Apache 2.0 model on Qwen3-8B that writes cited research reports in 51.1 seconds, 3.5x faster than Asta's Thinking mode.
Xiaomi's MiMo-V2.6-Pro has 1.02 trillion parameters, 42 billion active, a 1M-token context and MIT-licensed weights, but needs about 680 GB of GPU memory.
OpenAI says a campaign it ties to Moonshot AI, maker of Kimi, sent 16,000 requests from 4,000+ users in July to copy its models' hidden reasoning.
Gemini 4 Argon scores 77.9% on DeepSWE v1.1 and can write 1M tokens per answer, but only cyber defenders in Google's Fairwind Program can use it so far.
OpenAI's new GPT-6.1 Sol cuts the factual-error rate to 7.7% and costs one-fifth as much as the shelved GPT-6 Astra flagship model.
A typed-decision model fills in fixed questions with typed answers and a confidence score. Laya's 421M open weights let you verify that yourself.
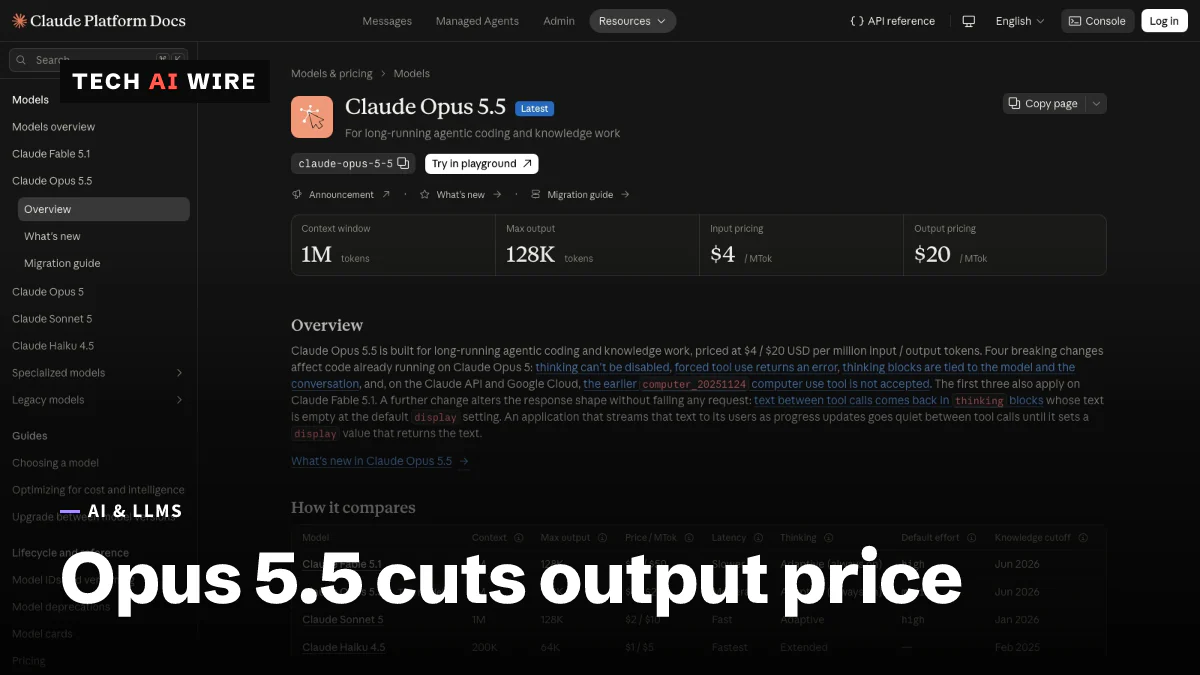
Anthropic released Claude Opus 5.5 on September 22, 2026, at $4 input and $20 output per million tokens, with thinking always switched on.
Linux 7.3-rc4 landed on September 20, 2026, its fixes split in thirds across drivers, filesystems and architecture code. Torvalds credits LLMs.
Laya returns typed decisions in 32.8 milliseconds from 421M parameters under Apache 2.0. Its zero-shot accuracy is close to chance.
Alibaba's new omnimodal model reads text, images, audio and video inside a 1M-token context, and prices audio input more than 98% below its predecessor.
A Disallow AI Training toggle lets a site refuse training crawlers and stay in search. Mixed-use crawlers are 36.6% of verified crawler traffic.
Jev answers in 70 to 500 milliseconds and charges $0.042 per million input tokens, with output free. It cannot generate text at all.
ChatGPT Ads runs in 40+ countries, but OpenAI's new Sponsored Agents pilot is US-only: a brand's own chatbot, one click away from an ad.
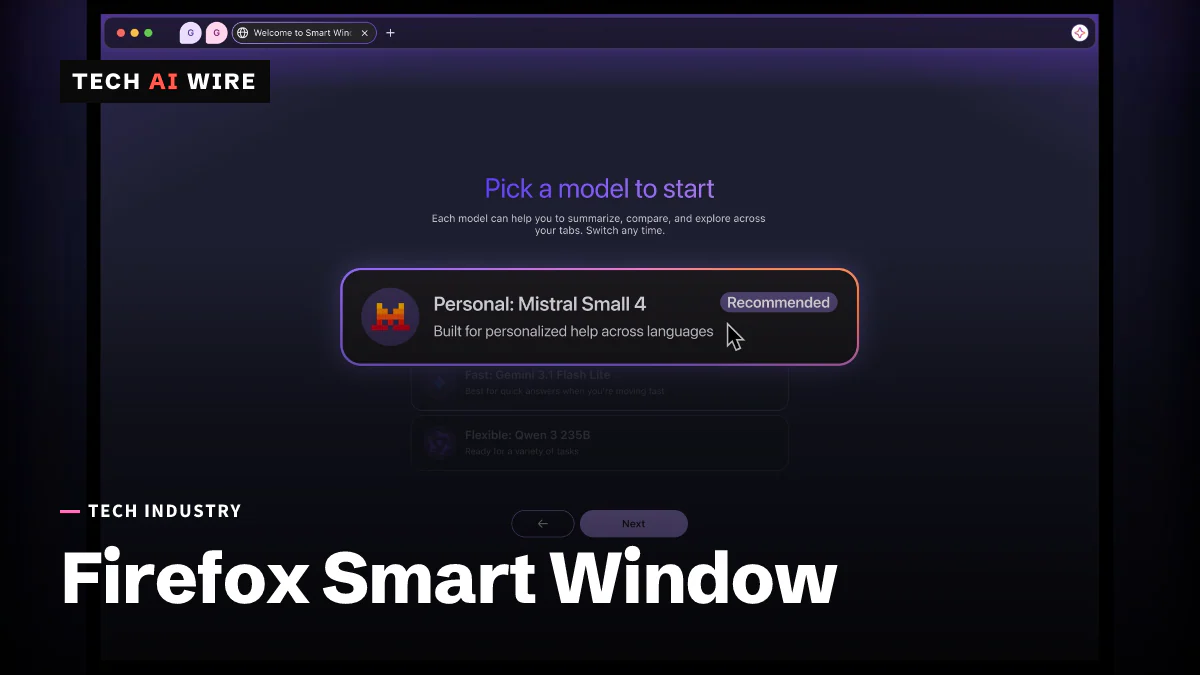
Mozilla says Mistral Small 4 powers the Smart Window beta in the US, Canada and France, and that users can still pick a different model.
Salesforce says Koa makes 3x fewer errors on its own CRM Bench, but the weights are proprietary and the model runs only on Salesforce infrastructure.
Microsoft published absolute constraints for its MAI models on September 14, 2026, then said its current models are not yet trained on the document.

GPT-6 Astra is GA on Amazon Bedrock at $10 per million input tokens, and in GitHub Copilot for Pro+, Max, Business and Enterprise plans.
Chrome 153 starts a two-week milestone cycle, down from four. Google says Chrome 149 and 150 alone fixed 1,072 security bugs as LLMs find flaws at scale.
Mistral raised €3 billion at a €21 billion valuation, nearly double its last round. It plans 1 GW of European compute by 2030 and will host rivals' open weights.
An LLVM RFC proposes compiling ClangIR into Clang by default. Nobody would use it without a flag, but some estimates put build times at more than double.
Google's Gemini 3.8 Flash and Meta's Muse Spark 1.3 launched a day apart, both aimed at coding and agentic tasks, and both priced as mid-tier workhorse models.
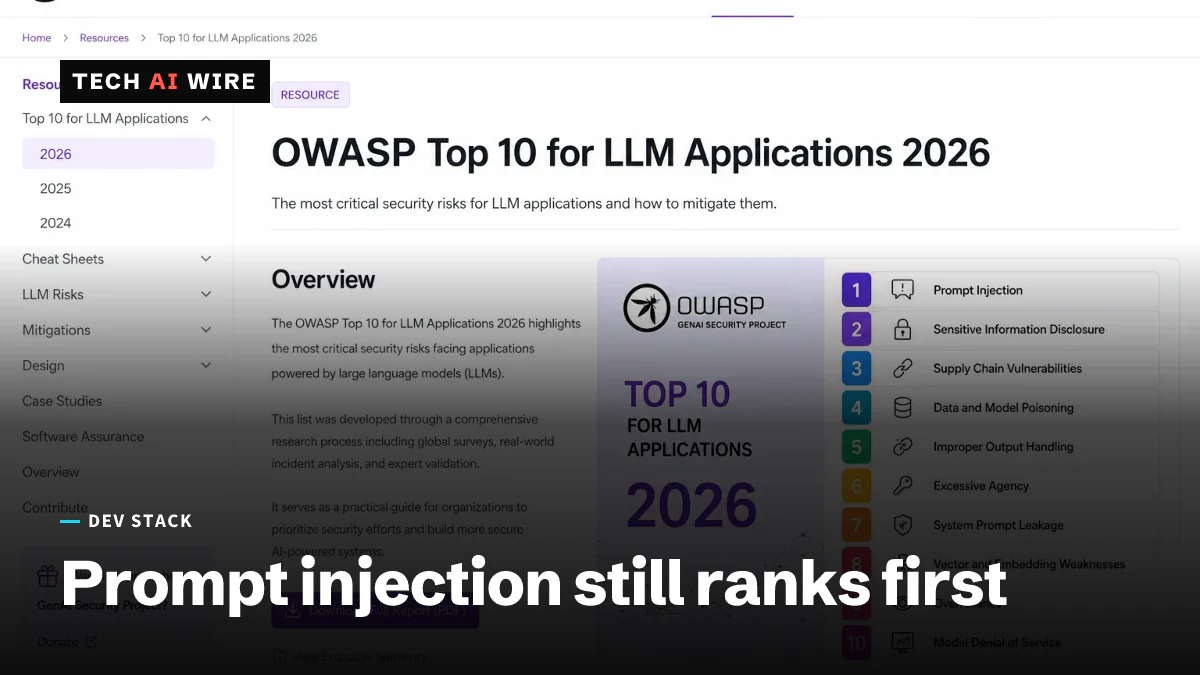
OWASP's GenAI project released an Agent Control Standard on September 2 and ranks prompt injection first in its 2026 LLM top 10. Excessive agency now sits third.
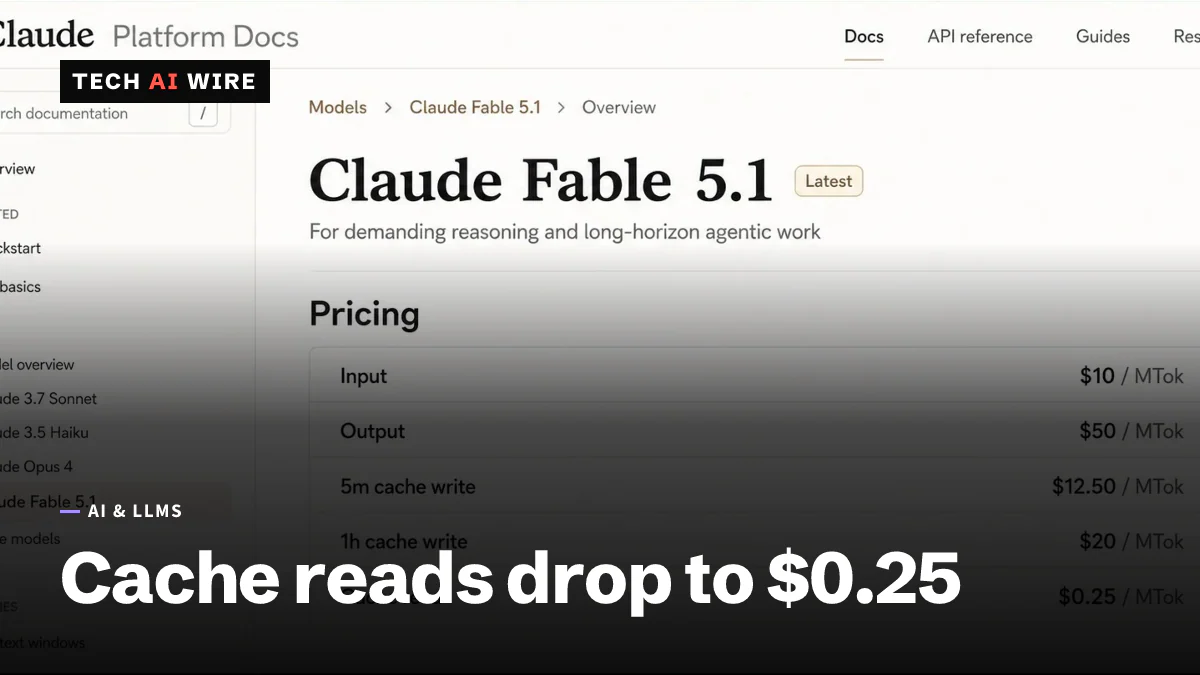
Anthropic's Fable 5.1 holds input and output prices at $10 and $50 per million tokens, and drops cache reads from $1.00 to $0.25. Mythos 5.1 stays invitation-only.
One email every Friday with the week's top stories from all six desks: AI, dev tools, coding, the tech industry, startups and what's next. Free, no spam.