Linux 7.4 makes idle workqueue flushes up to 100x faster
Linux 7.4 merges a workqueue fix that took idle flushes on a 192-CPU server from 40,000 to 4.2 million a second. Busy flushes can be 15-20% slower.
3 min read
By the numbers
- spent per XFS flush on a 128-CPU machine before the fix
- 64us
- idle flushes a second on a 192-CPU server, up from 40,000
- 4.2M
- slowdown for busy flushes on unbound workqueues
- 15-20%
Linux 7.4 has merged a workqueue change that makes flushing an idle workqueue 10 to 100 times faster on large machines, Phoronix reported on October 22, 2026. The fix by kernel developer Tejun Heo targets servers with many CPU cores, such as Intel Xeon and AMD EPYC systems. On those machines, a routine filesystem operation was wasting time checking every CPU, even when nothing was waiting.
What a workqueue flush is
A workqueue is the kernel's way of handing small jobs to background worker threads instead of doing them right away. Drivers and filesystems use it constantly. To flush a workqueue means to wait until every job already queued on it has finished.
Each workqueue connects to its worker threads through pool workqueues, or pwqs. A pwq is the link between one workqueue and one pool of workers. On a big server there can be one pwq for every possible CPU.
The problem traces back to an earlier kernel commit, "workqueue: Make unbound workqueues to use per-cpu pool_workqueues." Since that change, a flush "walks one pwq per possible CPU, cycling each pool lock," according to the patch series cover letter. It does that even when the workqueue is idle. More cores meant more wasted work on every flush.
Who found it, and where it hurt
Yao Kai, a Huawei engineer, reported the overhead in early September, Phoronix says. The pain point was XFS, a widely used Linux filesystem. XFS flushes one of its workqueues, the CIL workqueue, on every log force, the moment it must write its journal to disk.
On a 128-CPU machine, that flush took up to 64 microseconds each time, according to the report. A microsecond is a millionth of a second, so 64 sounds small. But a busy filesystem forces its log very often, and the cost added up.
The fix keeps track of which pwqs were actually used since the last flush, in per-node lists. A node is a group of CPUs with its own local memory. A flush now visits only those active pwqs. The series has two patches, "workqueue: Maintain pwq->total_in_flight" and "workqueue: Make flush_workqueue() visit only pwqs active since the last flush."
The benchmark numbers
The patch series reports its results from a 192-CPU machine with two nodes. Per-cpu workqueues run jobs on a chosen CPU; unbound ones let the scheduler pick any CPU.
| Test on a 192-CPU, 2-node server | Before | After |
|---|---|---|
| Flushing an idle per-cpu workqueue | 40,000 a second | 4.2 million a second |
| Flushing an idle unbound workqueue | 450,000 | 4.3 million |
| 16 threads queueing and flushing, per-cpu | 30,000 flushes a second | 110,000 flushes a second |
| 16 threads queueing and flushing, unbound | 60,000 flushes a second | 180,000 flushes a second |
The trade-off is stated plainly. "Dense flushes with every pwq active are unchanged on per-cpu workqueues and 15-20% slower on unbound ones," Heo wrote in his commit message, as quoted by Phoronix. Queueing new work is not affected.
The fix is already traveling beyond mainline. On September 9, Yao Kai posted a backport of the two patches to the openEuler kernel mailing list, aimed at openEuler's 6.6-based kernel.
Linux 7.4 is collecting other speedups in this merge window too, including a patch that opens files 39% faster in tests and Intel TDX Dynamic PAMT, which saves server RAM.
What this means for developers
Most people will never call a workqueue flush directly. They will feel this through the filesystem and drivers on large servers.
- Re-measure XFS on high-core machines. If you run XFS on servers with 100 or more CPUs, compare log-heavy workloads on Linux 7.4 against your current kernel. Workloads that sync to disk often are the place to look.
- Check for the busy-flush cost. Code that flushes unbound workqueues while every pwq is busy can be 15-20% slower. Kernel developers with such hot paths should benchmark them before and after.
- Do not expect gains on small machines. The saving comes from skipping idle pwqs. A laptop with a few cores had little to skip.
- Watch your distribution's kernel. openEuler is already backporting the series to its 6.6 kernel. Other enterprise distributions may follow, so check their changelogs if you cannot move to 7.4.
Sources
- Linux 7.4 Workqueue Changes Bring A "10 To 100 Times Faster" Optimization - Phoronix
- [PATCH OLK-6.6 0/2] workqueue: Make flush_workqueue() cost scale with active pwqs - openEuler kernel mailing list
Related articles
Torvalds' page cache patch reworked: 4.5x faster on ext4
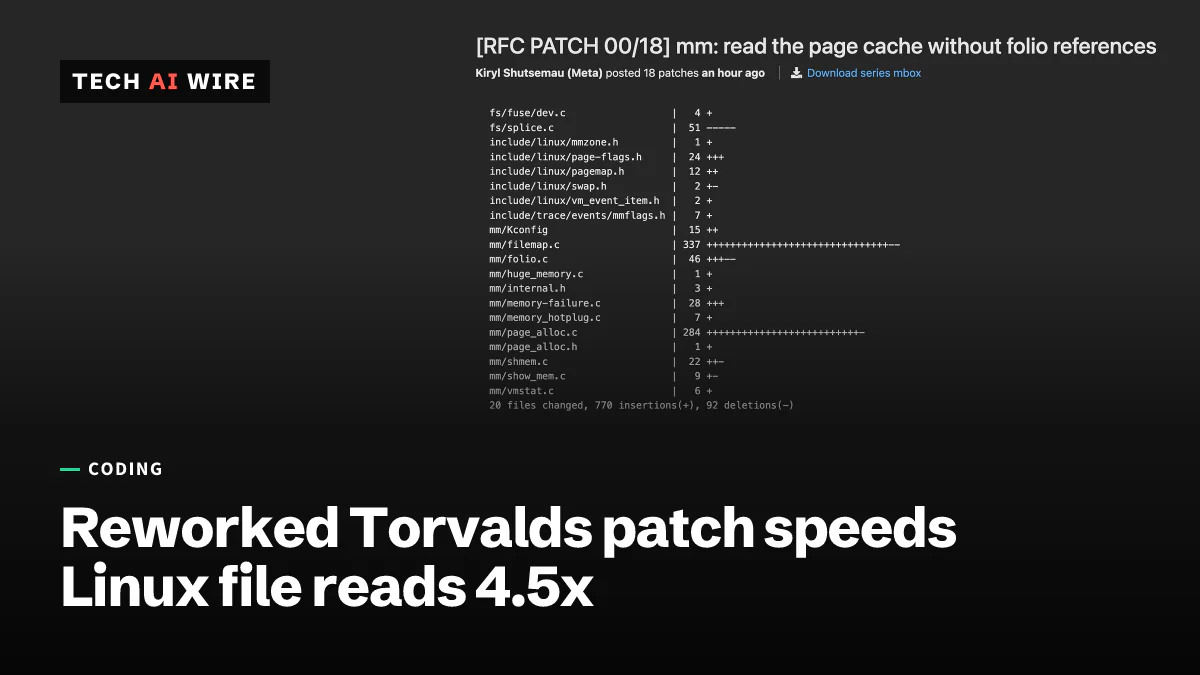
Meta's Kiryl Shutsemau turned Torvalds' page cache patch into an 18-patch RFC. 64 threads on ext4 rose from about 15M to 70M small reads a second.
BeamFS RFC: a Reed-Solomon file system for Linux
BeamFS, an 18-patch Linux RFC, stores every block as Reed-Solomon codewords so it can repair flipped bits on a single disk, at a cost of 7% of the space.
Linux 7.3 released with fchroot, failfs and faster Btrfs
Linus Torvalds released Linux 7.3 on October 18, 2026: 18,765 commits from 3,021 developers, new sandboxing tools and Btrfs fsync up to 5x faster.
The weekly digest
One email every Friday with the week's top stories from all six desks: AI, dev tools, coding, the tech industry, startups and what's next. Free, no spam.