Torvalds uses Claude Code to rework the Linux page cache
Linus Torvalds posted eight Linux kernel patches made with Claude Code. On his laptop, 8-thread small reads used about 4x fewer CPU cycles each.
4 min read
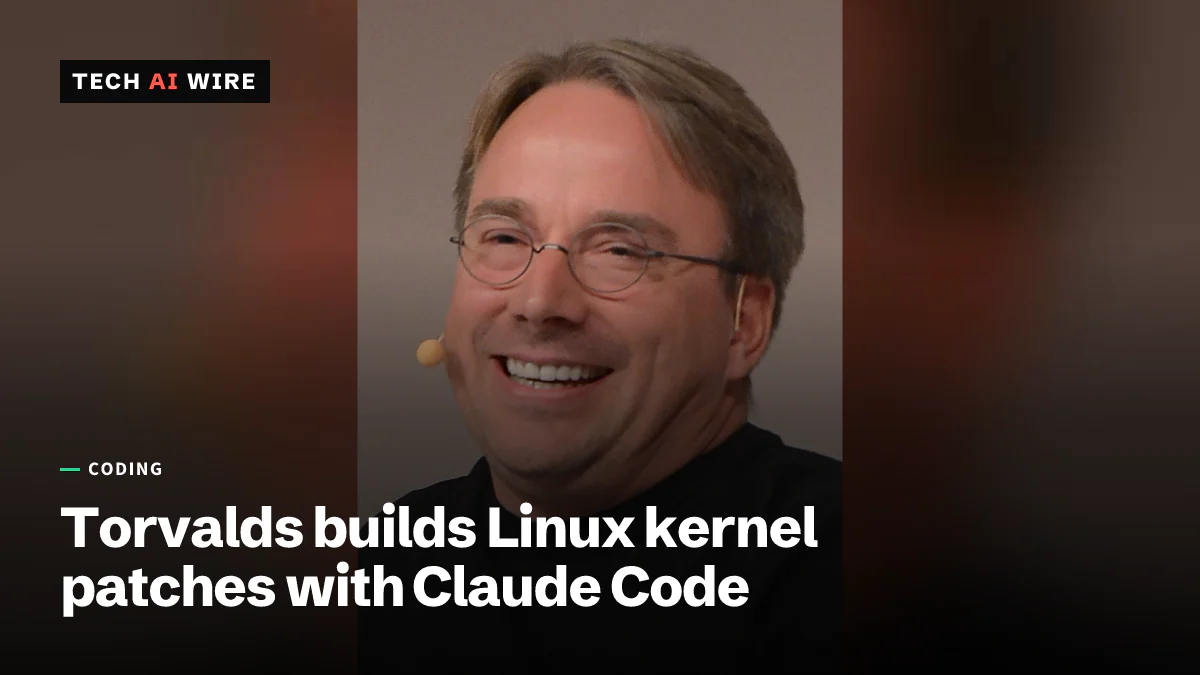
Linus Torvalds, the creator of Linux, has published a set of kernel patches that he says were written with Claude Code, Anthropic's AI coding assistant. The eight patches change how Linux reads small pieces of files that are already in memory. On his laptop, eight threads reading the same file used about four times fewer processor cycles per read. Nothing is merged, and Torvalds lists ten open problems.
What Torvalds published
The patches sit on a branch called noref-filemap-read-with-llm in Torvalds' own kernel tree. A branch is a line of changes kept apart from the main code. The eight code patches are dated October 7 to 10, 2026, and build on Linux 7.3-rc6, a test release.
The series description is plain about the AI's role.
The code, the test programs, the review behind the list above and the first draft of this text were done with an LLM coding assistant (Claude Code) under my direction. The measurements were run on my machine.
Each code patch carries an "Assisted-by: LLM" line next to his own sign-off.
Hardware Busters, a hardware news site, reported the branch on October 12 and notes it was measured on one laptop only.
Last month, Torvalds credited LLMs with catching bugs fixed in Linux 7.3-rc4.
The problem the patches solve
Linux keeps recently used file data in memory, in an area called the page cache, so it does not have to read the disk again. Every read from that cache briefly marks the memory as "in use" and then unmarks it. That mark is a counter stored with the page.
When many threads read the same small file at once, they all update that one counter. Each processor core has to take the same piece of memory in turn, which slows everyone down. Torvalds measured that 99.92% of this cross-core traffic landed on a single line of memory.
Hardware Busters says Matthew Wilcox first raised the problem in 2024. According to Torvalds, earlier fixes copied the data to a temporary buffer and checked it afterwards, but stalled on rare cases the check could not catch.
How the patches work
When a page leaves the page cache, Linux now waits before handing that memory to anyone else. It waits for an RCU grace period, a short window after which every reader that started earlier is known to have finished. RCU, short for read-copy-update, is a kernel method that lets readers work without locks.
Because the memory cannot be reused while a reader still looks at it, the read no longer needs the counter. Data is copied straight to the program. Earlier attempts tried to catch rare unsafe cases after the copy. "Deferring the free removes those cases instead of detecting them," Torvalds writes. If anything unusual happens, such as a missing page or the end of the file, the code falls back to the old path.
The numbers
All figures come from one laptop with an Intel Core i7-8565U, which has 4 cores and 8 threads. Each test read 16 bytes from a one-page file. Torvalds warns that the laptop slows down when hot, so cycles per read are fairer to compare than reads per second.
| Test | Before | After |
|---|---|---|
| 1 thread, kernel cycles per read | 452-454 | 408-409 |
| 8 threads, kernel cycles per read | 2,937-2,975 | 725-726 |
| 8 threads, reads per second | 9.9-10.4 million | 30-33 million |
| 8 threads, cross-core memory conflicts (perf c2c) | 30,538 | 101 |
| 1 thread, read into a buffer not yet in memory, cycles | 4,117-4,188 | 6,543-6,593 |
The last row is the cost: when the program's buffer is not yet in memory, the new path fails once and falls back. "A machine with more CPUs, or more than one socket, should gain more; nothing bigger has been measured," Torvalds writes.
What is still unsolved
Delaying reuse leaves some memory idle. In one test, four processes quickly freed parts of an in-memory file. The average memory left waiting fell from 565 MiB to 15 MiB after two extra patches. Those patches force a faster grace period once more than 1,024 pages wait on one processor. "The limit of 1024 pages is a guess," Torvalds writes.
His list of known problems includes:
- The memory allocator cannot see the waiting pages, so the out-of-memory killer may act while hundreds of MiB are about to come free.
- Requests for large blocks of contiguous memory can now fail with a "busy" error.
- Test suites such as xfstests, lockdep and KASAN have not been run, and no machine except his laptop has been tried.
- On the scheduler, he writes: "I am not sure this is the direction."
He calls the memory question "the part of this series that is least solved."
What this means for developers
- Nothing changes yet. The branch is not merged, and its description names no target release.
- Watch the review. Replies from memory, RCU and scheduler maintainers will decide whether it lands, changes or is dropped.
- Busy readers gain most. The measured case is many threads reading one small cached file. Teams running that workload on many-core servers should test it.
- A template for AI-assisted patches. Torvalds named the tool, signed every patch himself, published his raw numbers and listed what he had not tested. Teams writing rules for AI-written code can copy that shape.
- Check monitoring tools. Fast-path reads skip a tracepoint and the usual "accessed" marking, so tools that count page cache hits would see fewer of them.
Sources
- mm: read from the page cache without folio references - Linux kernel (git.kernel.org)
- Linus Torvalds Uses Claude Code to Rework the Linux Page Cache, Tripling Small-Read Throughput - Hardware Busters
Related articles
YSERVER 1.7 adds Vulkan 1.2 and cuts 4K VRAM use
YSERVER 1.7 cuts 4K VRAM use from 2-4GB to about 1.2GB, near X.Org's 0.9GB, and adds Vulkan 1.2 support for older Intel graphics.
Linux 7.4 kbuild patches cut kernel build times
A kbuild series aimed at Linux 7.4 cuts no-op builds by roughly 80% and trims 37.6 seconds off a full allmodconfig rebuild.
Zig 0.17.0 brings a split build system and fast rebuilds
Zig 0.17.0 landed on October 2 with 925 commits from 206 contributors: a reworked build system, incremental builds on x86_64 Linux, and LLVM 22.1.8.
The weekly digest
One email every Friday with the week's top stories from all six desks: AI, dev tools, coding, the tech industry, startups and what's next. Free, no spam.